ES|QL KNN function
Finds the k nearest vectors to a query vector as measured by a similarity metric.
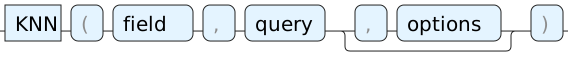
field- Field that the query will target. knn function can be used with dense_vector or semantic_text fields. Other text fields are not allowed
query- Vector value to find top nearest neighbours for.
options-
(Optional) kNN additional options as function named parameters. See knn query for more information.
Finds the k nearest vectors to a query vector, as measured by a similarity metric. knn function finds nearest vectors through approximate search on indexed dense_vectors or semantic_text fields.
The KNN function performs approximate kNN search
on indexed dense_vector and semantic_text fields. It delegates search to the underlying vector search index,
such as disk_bbq.
KNN also works on dense_vector expressions that aren't backed by an index, such as vectors generated by the
DENSE_VECTOR command. On an expression, KNN behaves differently:
- It performs an exact search that compares the query vector with the vector in every row. It doesn't build a vector index.
- It supports only the
similarity,similarity_function, andboostoptions. It ignores other options, such ask,min_candidates, andvisit_percentage. - The
similarity_functionoption sets the similarity metric. The accepted values arecosine,dot_product,l2_norm, andmax_inner_product. - If you don't set
similarity_function,KNNuses the similarity of the inference endpoint that produced thedense_vectorexpression or the query vector. If it can't infer one, it usescosine. - If the expression and the query vector come from inference endpoints with different similarities, the query
fails, even if you set
similarity_function. - If you set
similarity, it keeps only rows that are at least as similar to the query vector as the threshold. - If you request
METADATA _score, it adds a score to the relevance score of each row. Scores range from 0 to 1, except withmax_inner_productor aboostother than 1. - Rows whose vectors have a different number of dimensions from the query vector are filtered out with a warning.
- With
dot_product, every vector must be unit length. Rows whose vectors aren't unit length are filtered out with a warning. - To get the k nearest vectors, sort and limit the results explicitly, for example
SORT _score DESC | LIMIT 10.
Learn more about using ES|QL for search use cases.
| field | query | options | result |
|---|---|---|---|
| dense_vector | dense_vector | named parameters | boolean |
| text | dense_vector | named parameters | boolean |
k- (integer) The number of nearest neighbors to return from each shard. Elasticsearch collects k results from each shard, then merges them to find the global top results. This value must be less than or equal to num_candidates. This value is automatically set with any LIMIT applied to the function.
boost- (float) Floating point number used to decrease or increase the relevance scores of the query.Defaults to 1.0.
min_candidates- (integer) The minimum number of nearest neighbor candidates to consider per shard while doing knn search. KNN may use a higher number of candidates in case the query can't use a approximate results. Cannot exceed 10,000. Increasing min_candidates tends to improve the accuracy of the final results. Defaults to 1.5 * k (or LIMIT) used for the query.
visit_percentage- (float) The percentage of vectors to explore per shard while doing knn search with bbq_disk. Must be between 0 and 100. 0 will default to using num_candidates for calculating the percent visited. Increasing visit_percentage tends to improve the accuracy of the final results. If visit_percentage is set for bbq_disk, num_candidates is ignored. Defaults to ~1% per shard for every 1 million vectors
similarity- (double) The minimum similarity required for a document to be considered a match. The similarity value calculated relates to the raw similarity used, not the document score.
rescore_oversample- (double) Applies the specified oversampling for rescoring quantized vectors. See oversampling and rescoring quantized vectors for details.
similarity_function-
(keyword) The similarity metric to use when
KNNruns on adense_vectorexpression (rather than an indexed field). See the function description for more details about the default value. This option is rejected when used with an indexeddense_vectorfield, where the field's mapping determines the metric. Accepted values:cosine,dot_product,l2_norm,max_inner_product.
from colors metadata _score
| where knn(rgb_vector, [0, 120, 0])
| sort _score desc, color asc
| color:text | rgb_vector:dense_vector |
|---|---|
| green | [0.0, 128.0, 0.0] |
| black | [0.0, 0.0, 0.0] |
| olive | [128.0, 128.0, 0.0] |
| teal | [0.0, 128.0, 128.0] |
| lime | [0.0, 255.0, 0.0] |
| sienna | [160.0, 82.0, 45.0] |
| maroon | [128.0, 0.0, 0.0] |
| navy | [0.0, 0.0, 128.0] |
| gray | [128.0, 128.0, 128.0] |
| chartreuse | [127.0, 255.0, 0.0] |